Thinking about bringing machine learning into your business but not sure which problem to hand it first? You are not starting from a blank page. Fraud scoring in banking, imaging triage in hospitals, predictive maintenance on factory floors, tenant churn models in property management, recommendation engines in every online store you use: dozens of machine learning use cases already run in production, with documented results behind them.
Adoption has followed. McKinsey’s 2025 global survey found that 88% of organizations regularly use artificial intelligence in at least one business function, up from 78% a year earlier. The teams seeing returns tend to start in the same place: a prediction that changes a decision somebody makes daily, such as which patient to flag, which transaction to hold, or which pallet to reorder.
Where does machine learning fit into your operation? This guide walks through the ML use cases that hold up in production, industry by industry, how to pick your first one, and what to expect when a notebook becomes a live system.
What Machine Learning Actually Does Inside a Business
Machine learning is the branch of artificial intelligence in which a system derives its own rules from historical data rather than following logic written by a developer. Feed a machine learning model 200,000 past invoices with their payment outcomes, and it learns which feature combinations predict a late payment. Nobody codes the rule "clients in this postal code with orders above $40,000 pay 19 days late." Machine learning models find it in the training data on their own, because they analyze data at a volume no team could review by hand.
Traditional software handles problems where the rules are known and stable. Machine learning models handle the rest: problems where the rules are unknown, shift weekly, or involve more variables than one person can track.
“Machine learning gives us this incredible ability to take messy, complicated data and transform it into powerful predictions that help us make smarter decisions.”
IBU Official, Machine Learning Algorithms – Practical Case Studies
The learning approaches behind most business systems
Almost every commercial deployment runs on one of five machine learning techniques. Common supervised learning algorithms cover the majority, and the distinctions matter most when you are deploying machine learning models rather than reading about them.
|
Approach |
What the model learns from |
Typical business problem |
Common algorithms |
|
Supervised learning |
Labeled data with known outcomes |
Churn prediction, credit scoring, demand forecasting |
Linear regression, logistic regression, support vector machines, gradient boosting |
|
Unsupervised learning |
Unlabeled data, with no target variable |
Customer segmentation, anomaly detection, data mining |
K-means clustering, DBSCAN, principal component analysis |
|
Semi-supervised learning |
A small labeled set plus a large unlabeled one |
Document classification, image labeling |
Self-training, label propagation |
|
Reinforcement learning |
Feedback from actions taken in an environment |
Dynamic pricing, route optimization, autonomous vehicles |
Q-learning, policy gradient methods |
|
Deep learning (architecture) |
Large volumes of structured and unstructured data |
Computer vision, speech recognition, large language models |
Deep neural networks, convolutional and recurrent architectures, transformers |
Deep learning algorithms earn their compute cost on complex tasks where raw signal beats tidy columns: reading a chest X-ray, transcribing a support call, running the perception stack in autonomous vehicles, of which self-driving cars are the visible case. Semi-supervised learning fills the gap when labels are scarce. Autonomous agents sit on top, taking multi-step actions such as pulling a report, reconciling it, and flagging exceptions rather than returning one prediction.
Machine Learning Use Cases by Industry and Function
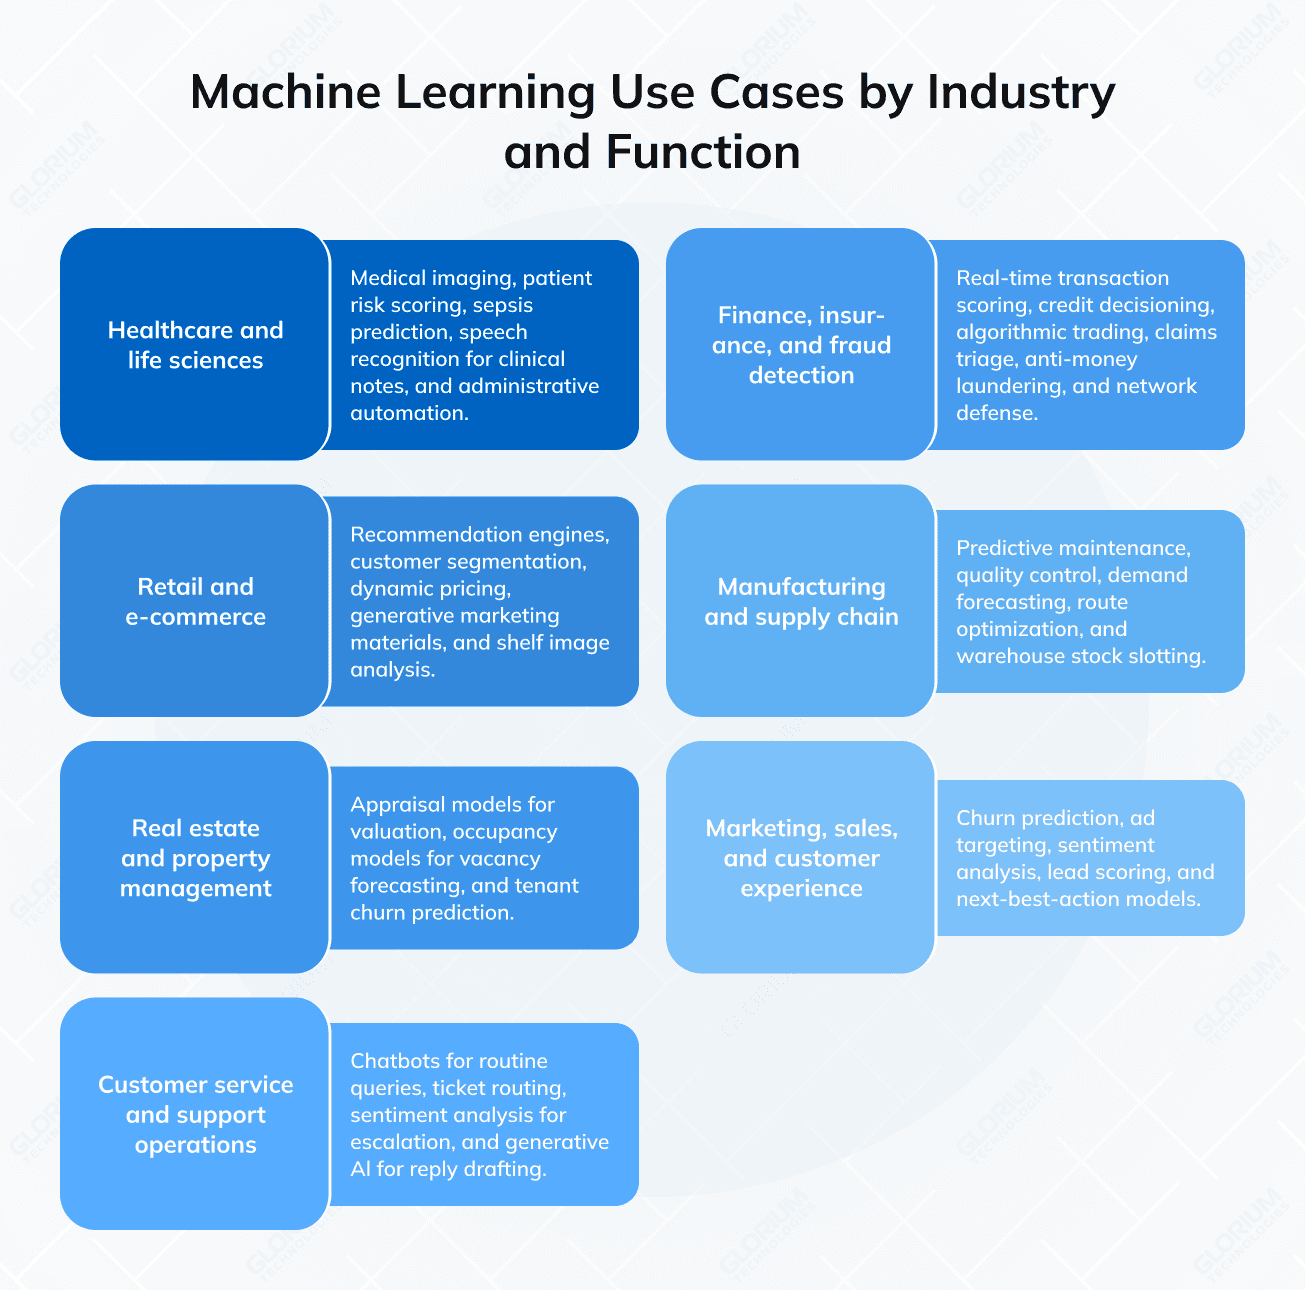
The strongest machine learning use cases share a shape: a repeated decision, a measurable outcome, and enough historical data to learn from. Machine learning use cases outside that shape stall in pilot. Education and agriculture run the same playbook, with dropout prediction and crop health monitoring as headline applications, but the real-world examples below come from the five industries with the most mature deployments, followed by two cross-cutting functions.
Healthcare and life sciences
Medical imaging is the most regulated and mature application of computer vision in commercial software. By the end of 2025, the FDA had authorized more than 1,450 AI-enabled medical devices, roughly 76% of them in radiology. Deep learning models trained on labeled data flag suspected lesions and triage worklists by urgency, and the same image recognition techniques analyze large volumes of pathology slides.
Beyond imaging, machine learning covers a wide slice of the clinical and administrative day:
- Risk scoring: Models flag readmission and sepsis risk from health records and device telemetry, the approach Geisinger Health System applied to sepsis prediction
- Population health: Machine learning systems surface patterns across thousands of encounters no clinician could review individually
- Clinical documentation: Speech recognition drafts notes from the consultation itself, so clinicians leave the room with a draft ready for review
- Administrative workflows: Natural language processing suggests billing codes and triages prior authorization requests
Our guide to machine learning in healthcare goes deeper, and our AI in healthcare practice handles the audit trail and change control that a proof of concept never surfaces.
Finance, insurance, and fraud detection
Fraud detection is the clearest case of machine learning paying for itself. Machine learning algorithms score transaction streams in real time, comparing each authorization against learned patterns of normal behavior for that customer, merchant, and channel. Credit card companies block suspicious charges in milliseconds without stopping legitimate ones.
The economics are stark. The LexisNexis True Cost of Fraud Study 2025 puts the total cost at $5.75 for every $1 of direct fraud loss at US financial services firms, up from $4.00 in 2021. The same study found that 44% of North American financial institutions still rely largely on manual review, and that gap is where automated fraud detection has the most room to work.
Other finance applications of machine learning include:
- Credit decisioning: Lending platforms analyze customer data on cash flow and behavioral signals beyond a credit score
- Algorithmic trading: Machine learning algorithms execute trades against learned patterns in historical price data
- Claims triage: Insurers route claims by predicted complexity before an adjuster opens the file
- Anti-money laundering: Unsupervised machine learning algorithms surface networks that rule-based systems miss
- Network defense: The same anomaly-detection logic learns normal behavior per user and device, catching credential misuse that signature-based tools miss
A global insurer came to Glorium Technologies with underwriters losing days to manual risk evaluation across fragmented sources. We built an AI risk management clearinghouse on Python and React, scoring exposure inside the underwriter's workflow. Risk evaluation now runs 40% faster, and our fintech AI development team handles similar work across banking and insurance.
Cybersecurity and threat detection
The anomaly detection logic behind fraud scoring transfers directly to security operations. The baseline changes from normal spending per cardholder to normal behavior per user, device, and service account, and the model flags the deviation.
Three applications carry most of the value:
- Behavioral detection: Models catch credential misuse and lateral movement that signature-based tools miss because the payload is new
- Alert triage: Classifiers rank alerts by predicted severity, which decides what an analyst opens first when the queue runs to thousands a day
- Vulnerability prioritization: Models score which known vulnerabilities are most likely to be exploited in your specific environment, rather than patching by CVSS score alone
Volume is why machine learning fits here. A mid-sized enterprise generates millions of authentication and network events a day, and the pattern that matters is usually a small deviation inside a normal-looking sequence.
Retail and e-commerce
Recommendation engines are the most visible ML use in retail, and Amazon and Netflix built the reference implementations. The machine learning algorithms behind them analyze data on which products co-occur in baskets, which sequences precede a purchase, and which substitutions a shopper accepts, raising average order value by putting the right item in front of someone at the right moment.
Four more applications carry retail deployments:
- Customer segmentation: Unsupervised learning groups shoppers by observed behavior rather than preset demographic buckets, and those segments feed campaign targeting and lifetime value forecasts
- Dynamic pricing: A reinforcement learning algorithm adjusts prices against demand, stock levels, and competitor moves
- Content production: Generative AI spins out marketing materials for testing at a volume a small team cannot match by hand
- Shelf monitoring: In stores, computer vision reads shelf images and flags a broken size run before a shopper walks away
Our AI in retail work covers that stack, from the data layer through the screen a store manager opens.
The upside is measurable. IHL Group puts the annual cost of retail inventory distortion, out-of-stocks and overstocks combined, at $1.73 trillion, and finds that retailers running AI and machine learning in these workflows grow sales 2.3 times faster than those that do not. Fewer than a quarter have rolled those models out where inventory distortion hits hardest, which is why shelf and demand use cases still clear internal approval quickly.
Manufacturing and supply chain
Predictive maintenance turns sensor readings into a failure forecast. Machine learning models watch vibration, temperature, current draw, and acoustic signatures, identify patterns that precede failure, and flag the part drifting toward it. Deloitte's smart manufacturing analysis puts the annual cost of unplanned downtime for industrial manufacturers at $50 billion, and reports 19% less of it for plants on predictive maintenance rather than fixed preventive schedules.
Upstream, demand forecasting delivers the same operational efficiency gain in supply chain management. McKinsey’s analysis of AI in distribution operations reports inventory cuts of 20% to 30%, logistics cost cuts of 5% to 20%, and procurement savings of 5% to 15%. Four applications carry most of that value:
- Quality control: Computer vision tools inspect parts on the line faster than any human inspector, catching surface defects and dimensional drift before a batch ships
- Inventory management: Machine learning reads purchasing patterns across thousands of SKUs, a scale at which weekly spreadsheet planning stops holding up
- Route optimization: Models like those behind Google Maps and Uber resequence deliveries against live traffic
- Warehouse slotting: Models assign stock to the slots that shorten pick paths for the crews working them
Plants pairing this with manufacturing software feed every model from one data layer.
Real estate and property management
Property portfolios generate exactly the repeated, recorded decisions machine learning handles well: which tenant renews, what a unit is worth, which applicant pays on time.
Four models do most of the work inside a property portfolio:
- Automated valuation: Appraisal models predict how location and building features move what a unit is worth
- Occupancy forecasting: Vacancy models surface exposure early enough to adjust rents
- Tenant churn scoring: Models rank tenants by renewal probability and name the factors behind each score
- Carrier selection: Models score carriers per lane on delivery reliability, damage rates, and invoice accuracy, which turns the annual rate negotiation into a conversation about measured performance
Acadian Group, a commercial real estate operator in New York, wanted to cut tenant churn without discounting across the board. Glorium Technologies built a tenant churn prediction system in Python with Scikit-learn, Pandas, and NumPy that scores churn probability per tenant and explains which factors move it. The pipeline beat the client's historical benchmarks, and Acadian uses the scores to decide who gets a renewal incentive.
Marketing, sales, and customer experience
Churn prediction protects revenue in any industry. A supervised model trained on historical account data returns a churn probability per customer plus the features driving it, which hands the retention team a ranked list and a reason to call.
Four adjacent applications shape the rest of the customer journey:
- Ad targeting: Models rank audiences on observed behavior rather than declared interests
- Sentiment analysis: Reviews and support tickets get scored so tone patterns surface before they reach a quarterly survey
- Lead scoring: Sales teams work a ranked list built on fit and engagement signals
- Next-best-action: Models suggest the offer or the step to take during a live call
Customer service and support operations
Chatbots built on natural language processing resolve most routine customer queries: order status, password resets, policy questions, appointment changes. The measurable win is response time, and faster first responses track closely with customer satisfaction scores, the customer experience metric most support teams watch.
Behind the front line, natural language processing routes tickets, sentiment analysis flags accounts where tone is escalating, and generative AI drafts the reply while a classifier decides who reviews it. Large language models have widened what automated customer service handles through an AI customer support agent, though reliable deployments escalate ambiguous cases.
Three numbers show whether the deployment works:
- Containment rate: The share of conversations resolved without a human
- Average handle time: Measured on the conversations that do escalate
- Satisfaction: Scored separately for contained and escalated conversations
Set the escalation trigger on model confidence, then tune that threshold against those three numbers instead of leaving it at the vendor default.
How to Choose Your First Machine Learning Use Case
Not every problem deserves a model. The filter Glorium Technologies applies to machine learning candidates during discovery has five steps:
- Find the expensive repetition: Decisions made hundreds of times a week where the outcome already gets recorded
- Apply the write-it-down test: If a person can state the rule in one sentence, automate it with plain logic and skip the model
- Check the data first: Confirm you hold labeled outcomes, not only activity logs
- Score your readiness: Existing automation, data quality, and whether anyone in-house can own the model after launch
- Pick the one that changes a workflow: A prediction pays back only when it lands where a team already works
Step two disqualifies more candidates than the other four combined, and catching it early saves a budget cycle.
How to measure whether the use case worked
Agree on two numbers before development starts: a model metric the data team tracks and a business metric the sponsor tracks. Pairing them stops a technically accurate model from passing review while the process it feeds stays unchanged.
- Fraud detection: Recall on confirmed fraud, paired with net fraud loss per million transactions
- Demand forecasting: Mean absolute percentage error against actuals, paired with inventory carrying cost and stockout rate
- Predictive maintenance: Lead time between the alert and the failure, paired with unplanned downtime hours avoided
- Churn prediction: Precision in the top-scoring decile, paired with revenue retained from accounts the team actually called
Validate both on a holdout period the model never saw in training. A model that scores well on the training window and then loses to the incumbent process in a live comparison has told you something useful before the rollout budget gets committed.
The same discipline applies to readiness. Score the candidate against four dimensions before committing:
|
Readiness dimension |
The question to answer |
A weak answer looks like |
|
Data coverage |
Do we hold recorded outcomes across at least one full seasonal cycle? |
Activity logs with no recorded result attached |
|
Process maturity |
Is the decision already made inside a system? |
The decision lives in email threads and personal spreadsheets |
|
Workflow ownership |
Which team receives the score, and in which screen? |
A new dashboard with no named owner |
|
Internal capability |
Who watches the business metric in month nine? |
The sponsor moved on, and nobody replaced them |
Business Benefits Companies Report from Machine Learning
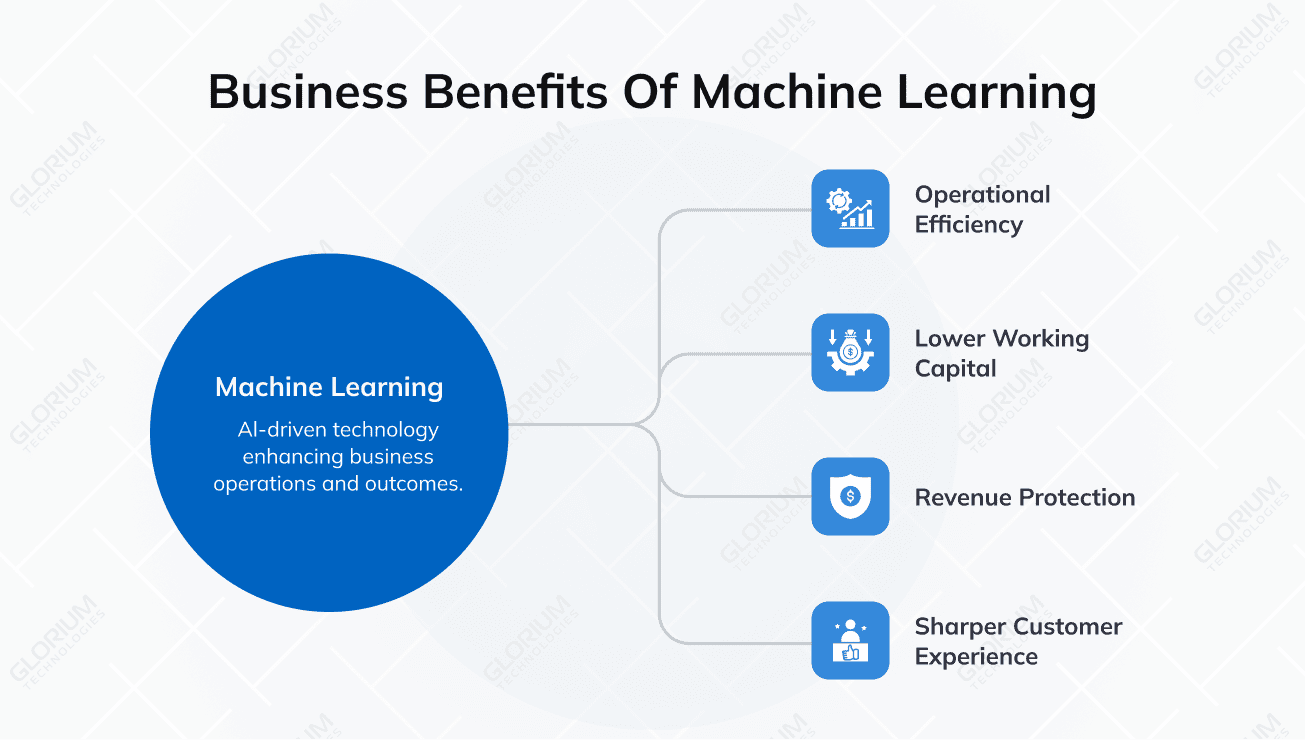
The ML use cases above cluster into four returns that drive positive business outcomes, each backed by the figures cited and by what artificial intelligence delivers in practice:
- Operational efficiency: 19% less unplanned downtime, per Deloitte, plus 5% to 15% procurement savings once repetitive tasks run on ML models
- Lower working capital: Inventory reductions of 20% to 30% in distribution, per McKinsey
- Revenue protection: At $5.75 of cost per $1 of fraud loss, every blocked transaction carries a multiple
- Sharper customer experience: Personalization and faster response improve customer satisfaction and retention without extra headcount
Implementation Challenges and How to Work Around Them
Machine learning solutions rarely fail on technology. They stall on data, on integration with existing business processes, or on ownership.
Data quality and access
Machine learning models learn whatever the training data teaches, gaps included, and every mislabeled data point becomes a rule applied at scale. Fragmented records across an ERP, a CRM, and three spreadsheets produce a model that validates well and fails in production, which is why big data services precede the model. Data governance carries compliance weight in regulated industries, where lineage and access controls are audit requirements.
Model bias and explainability
Bias in training data produces biased predictions, and in lending, hiring, and clinical settings, that exposure is legal as well as reputational. Tooling showing which features drove a prediction is standard practice now.
Feature attribution methods name the drivers behind an individual score. SHAP values suit the tabular models behind credit and churn decisions, Grad-CAM highlights the image regions that drove a computer vision output, and lending decisions in the US carry a separate obligation to produce adverse action reason codes a customer can read.
Fairness testing follows the same pattern. Evaluate accuracy separately across the groups the decision affects, before deployment and after every retraining, because aggregate accuracy hides a model that performs well overall and poorly for one segment.
Integration with existing business processes
A prediction nobody acts on has no value. The question is where the score lands: a separate dashboard, or the queue the retention rep already works.
Cost, compute, and talent
Training deep learning models consumes budget, and experienced machine learning engineers and data scientists are scarce.
Model drift after launch
Accuracy decays after deployment because the world the training data described keeps moving. Customer behavior shifts, a supplier changes packaging, a fraud ring finds a new pattern.
Two signals catch the decay early: drift in the distribution of the input features, and a falling share of high-confidence predictions. Watch both alongside the business metric, since the model can look healthy while the outcome it drives quietly deteriorates.
Retraining cadence follows how fast the underlying behavior moves. Fraud and pricing models typically retrain monthly, demand and churn models quarterly, and appraisal models in slower markets once or twice a year. Set that schedule during deployment rather than after the first complaint about accuracy.
Where Machine Learning Is Heading Next
Four shifts are reshaping roadmaps. Generative AI now writes the briefing around the number predictive models produce, and explainable AI is becoming a procurement requirement in finance and healthcare. Edge machine learning moves inference onto the device, processing data locally wherever latency constrains the design, from medical hardware to autonomous vehicles. Real-time analytics and robotic process automation are replacing overnight batch scoring.
Agents differ from the models above in what they hand back. A predictive model returns one number that a person then acts on. An agent carries out the next steps too, pulling the report, reconciling it against the ledger, and escalating only the exceptions it cannot close. That shifts the design question from prediction accuracy to which actions the system is permitted to take without review.
Build Your Machine Learning Solution with Glorium Technologies
Machine learning solutions ship or stall on three answers: which decision is worth modeling, whether your records can support it, and who owns the model in month nine. Getting those wrong is how two-thirds of organizations end up with a pilot nobody scaled.
Those are the questions we work through before anyone writes code. Glorium Technologies has engineered software for over 15 years, with deep specialization in healthcare and real estate alongside fintech, retail, and manufacturing. Artificial intelligence, data analytics, and machine learning sit at the center of that portfolio. Our machine learning services cover exploratory data analysis, data visualization, feature engineering, model training and validation, deployment, and the monitoring that keeps ML models honest.
Ready to put a number on it? Get an AI project estimate, or contact us for a consultation on where machine learning fits your roadmap.
FAQ
What do we need to prepare before a machine learning project starts?
Three things: access to the historical records that hold your outcomes, one person who knows how the decision gets made today, and agreement on the business metric the model has to move. Glorium Technologies handles the rest during the discovery phase, where our team audits data coverage, label quality, and integration points before anyone commits to a scope or a budget.
Can machine learning models run inside the systems we already use?
Yes, and that is usually where they belong. A score that lands in your CRM, ERP, or EHR queue reaches the person who acts on it, so we build it into the screen your team already opens. Glorium Technologies has engineered software for over 15 years, and our machine learning services team delivers the model together with the pipelines, APIs, and interface work around it.
Should we build a custom model or use an off-the-shelf AI API?
Pretrained APIs handle general tasks well: transcription, translation, document parsing, and standard image recognition. Custom models earn their cost when the pattern belongs to your data, such as churn in your customer base or defects on your line. Glorium Technologies maps that split during discovery and often combines both, using a vendor API where it fits and building only the parts that depend on your history. Our data science team runs that assessment before development starts.
How does Glorium Technologies keep a machine learning model accurate after launch?
We set the retraining cadence during deployment rather than after the first complaint about accuracy, watch feature drift and confidence distribution alongside the business metric, and hand over monitoring your own analysts can read. Clients who want the engineering half covered long term keep an internal owner on the outcome and a dedicated development team from our side on retraining and support.
How does Glorium Technologies handle machine learning in regulated industries?
Healthcare and real estate are our deepest verticals, alongside fintech, retail, and manufacturing, so data lineage, access control, and change management belong to the build rather than a later audit fix. For a global insurer, we delivered an AI risk management clearinghouse that scores exposure inside the underwriter’s workflow and made risk evaluation 40% faster. Our AI in healthcare practice applies the same discipline to clinical deployments, where every prediction has to be traceable.
About Hanna Reshetniak